Choose Multimodal Data by Model Requirement
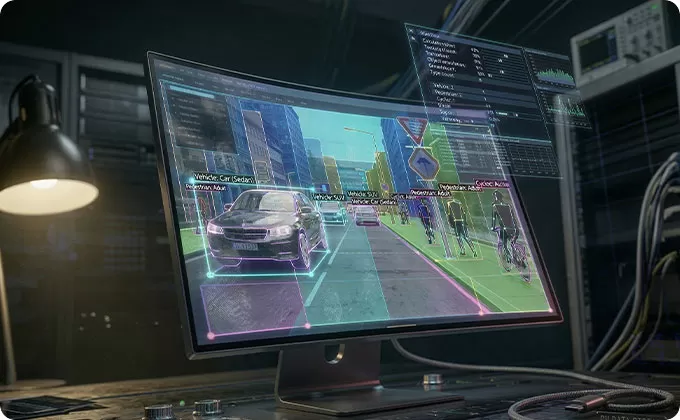
Start with the outcome your model must support. KeyCore can prepare aligned image-text, audio-text and video-text data, cross-modal annotations, and sensor metadata.
Questions to answer before choosing
• Is the data for a vision-language model, multimodal assistant, retrieval system or sensor-fusion model?
• Does suitable aligned data exist, or must KeyCore collect it?
• Which modalities, languages, environments and edge cases must the data cover?
• What alignment, labels, metadata and acceptance criteria does the model pipeline require?
Review KeyCore’s NLP and training-data solutions or contact KeyCore for a multimodal data review.